Showing posts with label DevOps. Show all posts

Sunday, 23 November 2014

Ruby and NO_PROXY

Proxy Servers


Like most people where they work there is always a proxy server present.  Love them or hate them they are here to stay. Recently where I am working we faced a problem. All the HTTP traffic is going thorough the proxy. However there was a specific case where we did not want it to.

The Problem


When we sent a request to a URL lets call it http://example.com (please note that this is an internal address) it would resolve to a load balanced address. For some reason (I'm not a networking guy) the proxy could not connect to it.

The Solution


What I needed to do was the following:

  1. I edited the /etc/hosts file and added IP_ADDRESS example.com
  2. I added export no_proxy="example.com" so it does not use the proxy. 
However the fun did not stop there. We were using Faraday to connect to this server. What I realised is that the default Ruby HTTP implementation does not honour no_proxy environment variable. So after some researching I found that httpclient does. So all I needed to do is install the gem and then use it:

conn = Faraday.new(url: 'example.com') do |faraday|
  faraday.request  :url_encoded
  faraday.response :logger
  faraday.adapter  :excon
end

Call conn.get and everything worked.

As I found it hard to find a solution I thought I would write it down for someone else to find it useful.

Saturday, 25 October 2014

Configuring Chef Development Environment

Background


At the current place that I am at one of the things that we are lacking is the concept of Infrastructure as Code. So I have decided to put my DevOps hat on and get the ball rolling.

I decided to use Chef as it feels more natural to me as a Ruby developer. The setup process was not as straight forward as I thought so I decided to document it, as I will forget later on.

Installation


  1. Download and Install Virtual Box.
  2. Download and Install Vagrant.
  3. Download and Install the Chef Development Kit.
  4. We are going to be using Berkshelf so we need to set this up:
    1. If you are using RVM find where RVM sets 'source "$HOME/.rvm/scripts/rvm"' after that place the following: export PATH=$HOME/.chefdk/gem/ruby/2.1.0/bin:/opt/chefdk/bin:$PATH
    2. Type which berks and you should get /opt/chefdk/bin/berks
  5. Lets create a cookbook to test out:
    1. Type berks cookbook chef-test
    2. Type cd chef-test
    3. Open up the Gemfile and remove gem 'berkshelf'
    4. Type bundle install
    5. Open up your Vagrant file and comment out 'config.vm.network :private_network, type: "dhcp"'
  6. Lets install some Vagrant plugins:
    1. Type vagrant plugin install vagrant-berkshelf
    2. Type vagrant plugin install vagrant-omnibus
  7. Lets fire up the cookbook by typing vagrant up.
  8. Profit!

Monday, 28 October 2013

AWS Elastic Beanstalk

AWS Elastic Beanstalk


During my last adventure we decided to use AWS Elastic Beanstalk. This technology from Amazon is a way to provide developers an easier way to manager their deployments, meaning this a PaaS. We used it for a Ruby on Rails application.

You can control your deployments from git and magically it will send your code and deploy it to an instance. So lets decipher some of this magic.

To get started using EB you need to AWS Elastic Beanstalk Command Line Tool. To set them up on your mac all you need to do is:

brew install aws-elasticbeanstalk

Once you have that setup to get yourself started is quite straightforward. All you need to do is follow the instructions here. As you can see this is pretty straightforward and very easy if you want to launch a basic site. However as I started to go deeper with this platform I realised that I would need do some more work. Why is that you ask? Well for two reasons:


  1. The flow of how you typically install a rails app is not exactly how the team at amazon designed it.
  2. A deployment always brings the site down.

Extending EB


One of the things that we quickly realised is that we needed to extend the platform. Luckily this was easy to do, the downside is that we were changing the internals of the scripts that were provided by Amazon. Luckily other people have encountered similar problems. So what I decided to do is create a repository where I could add these extensions that we needed to do to make sure it would work.

Please have a look here. There are some interesting things that needed to be done in order to make it work. If you need a further explanation don't hesitate to reach out.

Deployments


As I mentioned deployments are really easy with EB if you don't mind bringing the website down. I fortunately don't believe that a site should go down for a deployment. What we needed to do is build a more robust deployment pipeline. Luckily for me I am a massive believer of Continuos Delivery. So we knew we had to build a deployment pipeline. We decided that we would build multiple stacks (QA, UAT, LIVE) each having 2 environments within them (A and B, this is modelled around Blue/Green Deployments)

To accomplish these deployments we built a tool called mist. This tool takes the pain away from the deployment and we were extremely proud of it as all the developers could easily deploy the latest or a specific version to an environment. I urge you to take a look at the code and tell me what you think.


The Future


As with any platform there is definitely room for improvement. EB is still considered beta (which in some peoples eyes this can be seen as not production ready). Here are some of the limitations that I hit:

  1. An old version of Amazon Linux is used https://aws.amazon.com/amazon-linux-ami/2012.09-release-notes/. Unfortunately upgrading the AMI breaks EB.
  2. The ruby version is ruby 1.9.3p286 (2012-10-12 revision 37165) [x86_64-linux]. This is quite old. Could not successfully upgrade this.
  3. EB uses Phusion Passenger. The version is Phusion Passenger version 3.0.17. This again is quite old too. Could not successfully upgrade this.

We did explore other avenues like JRuby and I fell in love with the platform. Give enough time I wanted to get EB to work with JRuby.

Hopefully this is of help to anyone else out there that is thinking of using EB with Ruby on Rails.

Saturday, 9 March 2013

Lean Projects - Part 2


So some people will read the previous blog and say why are you being so negative? See I don't see it that way, I see it as a place that has a great culture that wants to embrace change and continuous improvement. I also see this as massive opportunity to try out some of the ideas that I will present. A lot of these ideas are not new topics, however they have been tailored for the environment that I am in.

The concept that I am calling this is Lean Projects. A way for us to embrace lean and agile methodologies in an agency environment.


Kanban


Kanban is a method for developing software products and processes with an emphasis on just-in-time delivery while not overloading the software developers. In this approach, the process, from definition of a task to its delivery to the customer, is displayed for participants to see and developers pull work from a queue.

The thing to note from the above statement is that Kanban works on the concept of a pull model.

Visualise Workflow


As stated above, one of the challenges that we face is to visualise our workflow. One way to get started is to map the value stream. The idea behind value stream mapping is to sketch out how you are working as this will help everyone to understand how the process works.

From this visualisation we can create what is called a Kanban board. The idea behind this board is to have a way to show your team what your value stream looks like. An example of a board looks like this:

This board is the single point of truth for everyone working on a product.

If you would like to know how to manage a process of the Kanban board, please read my previous blog Launching Australia's Biggest News Site

Limit Work In Progress


The most important part of the Kanban process is to limit your WIP.

In Kanban, we don’t juggle. We try to limit what we are doing, and get the most important things done, one by one, with a clear focus. It’s not uncommon to find that doing ten things at once takes a week, but doing two things at once takes hours, resulting in twenty things being done by the end of the week.

A great explanation can be found here Why Limit Work In Progress?


Measure and Manage Flow


The important aspect is to make sure that each of the features that is on the board actually goes through to the last step of your flow. We set limits to make sure we don't start picking up more features than the ones already started.

Some teams have the concept of stop the line, where the team gets together to make sure the pipeline clears up for the next features to be pulled in.

Fortunately Kanban has a few ways for us to measure the pipeline, as without measurement we can't improve on things.

Cumulative Flow Diagrams


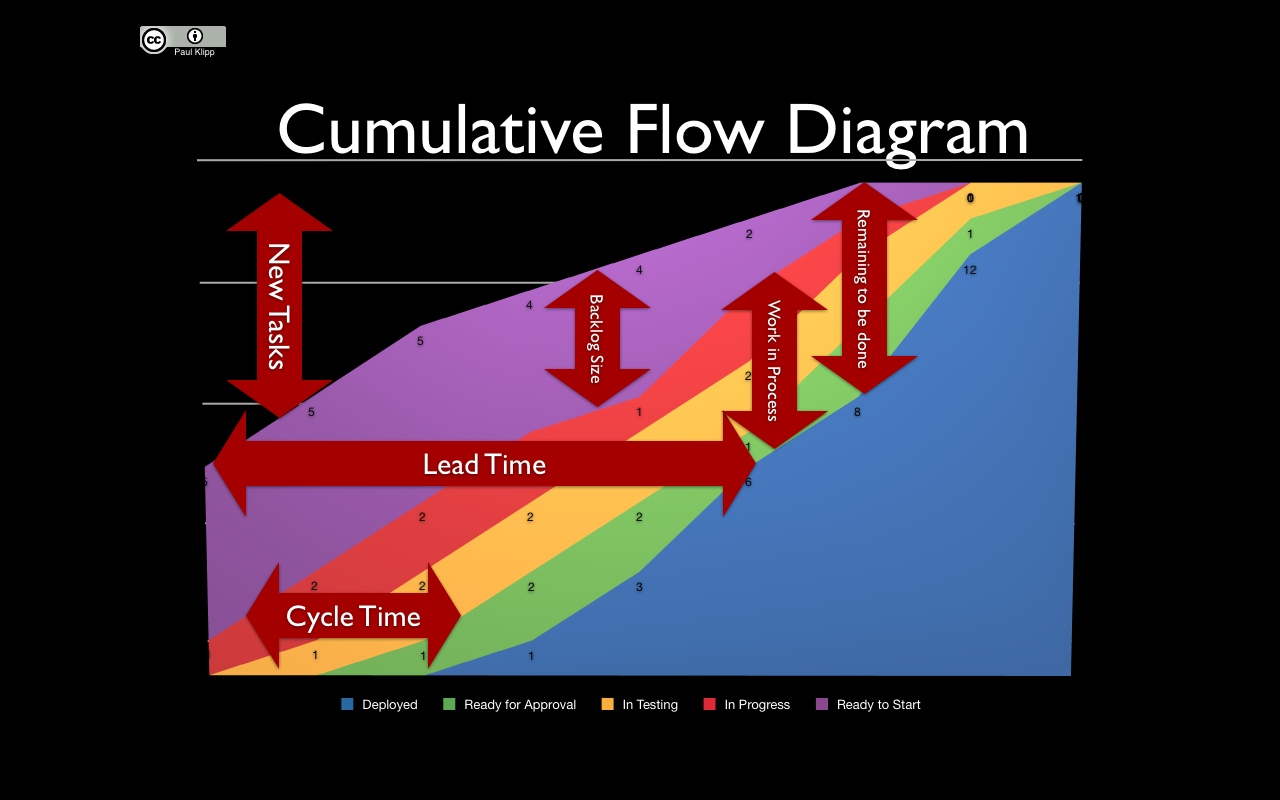
This diagram is an area graph that depicts the quantity of work in a given state, showing arrivals, time in queue, quantity in queue, and departure. This is a great way to visualise how we are churning features through our work flow.


Lead Time


The term lead time (LT) is just a fancy way to say time to market. It’s essentially the time that elapses (on the calendar) from something is ordered until it is received. In software development, a feature is ordered when someone (like the product owner) asks someone else (the team) to implement it. The same feature is received when it is deployed to the production system and ready to be used by end users.

Why is this important? Well, we can track how long a feature took. This is a really powerful metric, as it can be used to eliminate the entering of hours spent into a system.

How can this be used in Lean Projects? Well when I estimate I always like to estimate in terms of effort, meaning that it is easier for me to think about how easy/hard something is rather than how long it will take. This effort for me is measured using t-shirt sizes, e.g. S, M and L. Now if we start tracking all the features that have been sized using a t-shirt size we can start measuring the lead time for each of these features. We can then take the average of the lead time and this amount can be used to drive the estimates of the next feature.

Make Process Policies Explicit


As mentioned on wikipedia:

Until the mechanism of a process is made explicit it is often hard or impossible to hold a discussion about improving it. Without an explicit understanding of how things work and how work is actually done, any discussion of problems tends to be emotional, anecdotal and subjective. With an explicit understanding it is possible to move to a more rational, empirical, objective discussion of issues. This is more likely to facilitate consensus around improvement suggestions.

LeanKit has a great example of how this can be achieved.

Feedback Loops and Improvement Opportunities


The way to improve this is to provide a way to have some form of feedback loop. I am big fan of Agile Retrospectives. The idea is to meet at a regular time to reflect on how everything is going. With Lean Projects we need to reflect on how efficient the process is and ask the right questions. The way that we can do that is by using the 5 Why's Technique. A good metric for improvement is reducing lead time, as this will help you deliver all features in a better way.

Remember to listen to your team as they are closer to the problem than we usually are. Usually issues tend to show that it is a process problem not a people problem. Lean Projects are about a bottom up approach.

Your people are your most important resource. Ensuring their support and cooperation is vital for all major projects.

Specification By Example


Specification by Example is a set of process patterns that facilitate change in software products to ensure that the right product is delivered efficiently.Wikipedia summarises this quite well:

Teams that apply Specification by example successfully commonly apply the following process patterns:
  1. Deriving scope from goals
  2. Specifying collaboratively – through all-team specification workshops, smaller meetings or teleconference reviews
  3. Illustrating requirements using examples
  4. Refining specifications
  5. Automating tests based on examples
  6. Validating the underlying software frequently using the tests
  7. Evolving a documentation system from specifications with examples to support future development

So what does this all mean for Lean Projects? Well the basic idea is that we want to find a common language to describe the requirements through as a set of examples. For this work we need to do this collaboratively and to make sure that the requirements don't become stale as they will serve as documentation.

Before we can think of an example, we need to think of the value that we are adding. The best format I have found is as follows:

In order to [business value]
As a [role]
I want to [some action]

The first part is the most important and it should reflect one of these values:

  • Protect revenue
  • Increase revenue
  • Manage cost
  • Increase brand value
  • Make the product remarkable
  • Provide more value to your customers

Also think about the role that this feature is for. The reason I mention this is because sometimes we build a feature for the “Highest Paid Person's Opinion”, which most of the time adds no value. A scenario or example has the following format:

Given [context]
When I do [action]
Then I should see [outcome]

The Given step is where you set up the context of your scenario. Every scenario starts with a blank slate. The When step is where you exercise the application in order to accomplish what needs testing. Finally, the Then step is where you verify the result.

This way of working can be though of as outside-in development. So an example feature would look like this:

Feature: Login

In order to access the website content
As a website user
I need to log in to the website

Scenario: valid credentials
Given I am presented with the ability to log in
When I provide the email address "test@mywebsite.com"
And I provide the password "Foo!bar1"
Then I should be successfully logged in

Scenario Outline: invalid credentials
Given I am presented with the ability to log in
When I provide the email address <email>
And I provide the password <password>
Then I should not be logged in
Examples
| email | password |
| test@mywebsite.com | Foo!bar2 |
| test@mywebsite.com | Foo |

Lean Software Development


Lean software development is a translation of lean manufacturing and lean IT principles and practices to the software development domain. Adapted from the Toyota Production System, a pro-lean subculture is emerging from within the Agile community.

Lean software development plays by seven principles.

Eliminate Waste


Waste is anything that interferes with giving customers what they value at the time and place where it will provide the most value. Anything we do that does not add customer value is waste, and any delay that keeps customers from getting value when they want it is also waste.

Some forms of waste are:

  1. unnecessary code or functionality
  2. starting more than can be completed
  3. delay in the software development process
  4. bureaucracy
  5. slow or ineffective communication
  6. partially done work
  7. defects and quality issues
  8. task switching

Build Quality In


The idea here is to start with the frame of mind that quality is important and needs to be done from the start. Your goal is to build quality into the code from the start, not test it in later. You don’t focus on putting defects into a tracking system; you avoid creating defects in the first place.

Extreme Programming is an excellent example of building quality in, some examples are:

Pair Programming


Pair Programming is an agile software development technique in which two programmers work together at one workstation. One, the driver writes code while the other, the observer, reviews each line of code as it is typed in. The two programmers switch roles frequently.

Test Driven Development


Test-driven development (TDD) is a software development process that relies on the repetition of a very short development cycle: first the developer writes an (initially failing) automated test case that defines a desired improvement or new function, then produces the minimum amount of code to pass that test, and finally refactors the new code to acceptable standards.

Continuous Integration


Continuous integration (CI) is the practice, in software engineering, of merging all developer workspaces with a shared mainline several times a day.


Refactoring


Code refactoring is a "disciplined technique for restructuring an existing body of code, altering its internal structure without changing its external behaviour", undertaken in order to improve some of the nonfunctional attributes of the software. Advantages include improved code readability and reduced complexity to improve the maintainability of the source code, as well as a more expressive internal architecture or object model to improve extensibility.

Create Knowledge


We have all been in the situation where we have only one person that knows the codebase. There will always naturally be individuals that are stronger than others in specific areas. This is what makes great cross functional teams, however having only one person know something is what is called a single point of failure.

It is important that the whole team has an understanding of how the system works, so that we can eliminate single points of failure. However this is easer said than done as not everyone is always interested in every aspect of every system.

The following provide great ways to create knowledge:


Defer Commitment


Emergency responders are trained to deal with challenging, unpredictable, and often dangerous situations. They are taught to assess a challenging situation and decide how long they can wait before they must make critical decisions. Having set a time-box for such a decision, they learn to wait until the end of the time-box before they commit to action, because that is when they will have the most information.

Basically we want to decide as late as possible, specially for irreversible decisions.

Deciding too early, you run the very likely risk that something significant will have changed, meaning your end product might meet the spec, but it might still be the wrong product! This is one reason why so many projects fail.

Deliver Fast


If we can deliver software fast that means we can get real feedback from actual users, which is the reason you are building the feature in the first place. Another really great side effect of delivering software fast is that you would have had to solve the way you release your features. In order to release quickly means that you need to do it in a repeatable way, this means automation. The way to achieve this is through continuous delivery.

Continuous delivery is a pattern language in growing use in software development to improve the process of software delivery. Techniques such as automated testing, continuous integration and continuous deployment allow software to be developed to a high standard and easily packaged and deployed to test environments, resulting in the ability to rapidly, reliably and repeatedly push out enhancements and bug fixes to customers at low risk and with minimal manual overhead.

Respect People


I think it’s important to treat everyone with the same respect, whatever their job. It doesn’t matter whether they’re the CEO, a developer, project manager, the receptionist or the cleaner, respect everyone equally.

This comes back to the bottom up approach, giving people the responsibility to make decisions about their work. It is important to build knowledge and develop people who can think for themselves.

Respecting people means that teams are given general plans and reasonable goals and are trusted to self-organise to meet the goals. Respect means that instead of telling people what to do and how to do it, you develop a reflexive organisation where people use their heads and figure this out for themselves.

Optimise The Whole


A lean organisation optimises the whole value stream, from the time it receives an order to address a customer need until software is deployed and the need is addressed. If an organisation focuses on optimising something less than the entire value stream, we can just about guarantee that the overall value stream will suffer.

Looking at the whole picture is important. In the past I have spent time just optimising the development practices, however I believe that if you don't love what you are building then what is the point. We should all care about the overall value stream.

Final Thoughts


All of these thoughts have been going around in my head for years and I am truly excited to put these ideas to work in such a vibrant environment. I look forward sharing my findings as I love to see how all these thoughts change over time.

Wednesday, 9 January 2013

Launching Australia's Biggest News Site


For years I had witnessed that the engineering practices have not been up to par with what the rest of the industry was doing. As a development team we weren't focusing on quality and every thing that we did was very manual. This caused me great discomfort so I began preaching on the values of agile and the practices from extreme programming that I have had success with in the past. For a while I felt it was going nowhere until certain key people were hired that made that journey easier (you know who you are).

The journey began early 2011 as we were faced with a difficult decision. We had built an internal CMS that has met our needs for the last 10 or so years. However as with many software solutions, the years have not been kind to it. This solution was basically built with one purpose, to build web sites. However we were facing the dilemma of multiple devices. Development was done through a text area and the code was not version controlled. We unfortunately hit a brick wall with it's capabilities. The question arose do we rebuild it or do we look at paid product?

Previous attempts to rebuild the CMS had pretty much answered that question, so we decided to start searching for a product. We needed a product that was extensible and was built using .NET so we thought the best product for us would be Sitecore.

To be successful from an engineering point of view, we wanted to accomplish the following:
  1. Build a new website using a new CMS product.
  2. Introduce quality into the product using TDD and BDD
  3. Implement DevOps
This was a very ambitious goal and a massive transformation.

We already were using Scrum within other projects, however we all agreed that this was not Scrum, more like mini waterfall. We were building things in sprints and releasing months later (due to technical and process issues). So we began to plan our first iteration.

Sprint Zero

People often underestimate the importance of sprint zero. We were one of these people. Don't get me wrong it's not like we just jumped into it. Our sprint zero looked like this:
  1. Get a backlog of features that we needed to build.
  2. Set up a continuous integration environment along with version control.
  3. Set up a source code structure.
What was the most important step we left out? We had not tackled the problem of releasing our software. The issue that we had was that we really didn't know where our solution would end up and we also knew that a feature would not be complete any time soon, so we left it. The lesson for me was, it is important to set up a process that will deploy software. As code that is sitting in version control is wasted.

Process

We started off with Scrum and implemented the following routine:
  1. Two week sprints
  2. Two hour planning meeting at the beginning using planning poker
  3. Sprint Review Meeting
  4. Sprint Retrospective
Our estimation was done using T-Shirt sizes and converted to points to track. We tracked our progress using burn-up charts. This approach measures the estimated value of points left vs actual points being delivered. To me this gives a false sense of progress. I think a better way to measure is how many stories you are doing in an iteration vs how many stories are left.

Our board was modelled around the Lean approach of mapping the value stream. We were also using LeanKit to measure Lead and Cycle Time. We later dropped LeanKit to use Jira with Greenhopper, however this turned to be more complicated that just using LeanKit. I enjoyed measuring these times as I found that having a conversation around statistics at your retrospective gives you a great way to talk about continuous improvement.

So what was the end result? Well we started using more of a lean approach using Scrumban. We had weekly sprints and we didn't have long planning meetings. We would try to raise issues as they appeared and put it on the board to remind us to tackle it and we would still have retrospectives every few weeks.

Story Writing/Use Cases

We were all big fans of User Stories Applied. So we started to write stories in the following format

As a <role>, I want <goal/desire> so that <benefit>

During the story writing session we realised that the last part of the story was often left out and Mike Cohn says that it is optional. I started to disagree, if you can't explain the reason is it really worth it? I think this format would have been better

In order to <receive benefit> as a <role>, I want <goal/desire>

This format puts the benefit first which I think it is important. We all know that a story is a promise for a conversation, however this was not always the case and conversations were left out.

The acceptance criteria was captured using gherkin language. Unfortunately this was easier said than done, as it was new and people in general find it hard to describe the system. Due to this the development team started writing the acceptance criteria. Unfortunately to me this felt completely wrong. The reason is as follows:
  1. Usually the rest of the team would not review the criteria (product owner, scrum master)
  2. The language would turn into developer speak, which means the rest of the team would not get it.
If the development team is going to write the specs I find it easier to follow your trusted way of testing as the overhead of the gherkin language is not worth it. One needs to remember that BDD is a collaborative approach.

Testing

As I mentioned above we held quality very high as a practice so we decided to have the following levels of testing:
  1. Unit Testing
  2. Integration Testing
  3. Acceptance Testing
We had some challenges with the testing:
  1. Unit testing is hard to achieve using Sitecore. So we had to create a thin abstraction around it.
  2. All of Sitecore is driven around configuration file (roughly 4000 lines). We had to customise the config file to be able to do integration testing. This proved that we weren't really testing the same system. Due to this we had to create a matrix of the parts that we could test and the parts that we should avoid, which is not ideal.
  3. Due to these complications we started writing more acceptance tests as Sitecore needed a full HTTP context to be present.
  4. Acceptance tests were sometimes written to hit an API and sometimes to hit the UI. This proved to be complicated as we now had tests that looked like integration tests so the line was blurred.
These challenges proved costly to us. The biggest cost is that to be able to release a change the build takes over an hour and some of our tests are flaky.

The lesson here is to always pay attention to the testing pyramid.

DevOps

This area of our journey proved to be the most difficult. The reason I say this is that culture needs to change for DevOps to be successful.

We are all big fans of Continuous Delivery so we wanted to make sure that we made this a reality. The biggest challenge that we faced was actually having somewhere to deploy our application to. Long story short we fought with some hosting providers and decided that to really embrace continuous delivery we needed to go to the cloud.

Here is a summary of the tools that we used to make DevOps a reality:
  1. Continuos Integration started with Bamboo, however this moved to Team City
  2. All the scripting was done using PowerShell. The reason for this is that our application is based on .NET and being deployed on windows. In hindsight writing PowerShell is easy, however maintaining a large codebase with tests and specs is very primitive. Looking forward we would use Ruby.
  3. We implemented our own package manager that is based on nuget. The package manager code is based of the following code. Moving forward I would consider to use Puppet
  4. All of our instances are prepared using Puppet and the initial infrastructure is set up using CloudFormation.
As mentioned previously our biggest challenge was to bring the two teams together. Some of the things that I found were as follows:
  1. Not everyone in operations believes they should be doing infrastructure as code.
  2. Not everyone in the development team cares about infrastructure as code and understanding infrastructure.
Due to the above reasons it is tempting for organisations to create a DevOps team. I don't agree with this as it is important for the organisation to come up with their definition of DevOps. If you know you don't have the right fit then go ahead and find it!

Conclusion

We had a great journey and have learnt so much about Agile, Continuous Delivery and DevOps. It wasn't always a smooth ride however we were able to pull it off and have lots of things that we can improve. Some areas that we want to concentrate on are:
  1. Design for failure.
  2. Implement Minimum viable product to justify the build of a feature.
  3. Implement a self healing system.
  4. Puppetise all of our infrastructure.

Friday, 24 August 2012

DevOps – Misunderstandings


DevOps – Misunderstandings


The DevOps movement has been an interesting and confusing term in our industry. I thought I would write about this because I had an interesting conversation at work and it seems that we all had different ideas of what this lovely word means.

Lets look at how Wikipedia defines it

DevOps is a software development method that stresses communication, collaboration and integration between software developers and information technology professionals. DevOps is a response to the interdependence of software development and IT operations. It aims to help an organisation rapidly produce software products and services


So what does this mean?


DevOps is purely a culture, a way of thinking and interacting.


The biggest confusion that I saw with my peers is that DevOps is a team that needs to be formed as a separate entity. This is wrong!


DevOps is collaboration between people from the development, operations and testing. This gathering is controlled purely by the nature of a self organising team. They don't report to a DevOps manager.


Another misconception that I noticed was that Infrastructure As Code is DevOps. This is wrong!


Infrastructure As Code came from the understanding that people were tired of having Snowflake Infrastructure and a lot of these problems have been solved in the development world. This really means that we are being pragmatic and solving our own problems by learning from each other. Infrastructure As Code is the key to implementing DevOps concepts.


Hopefully this clarifies some of the misunderstandings, you can find further information about DevOps can be found here.

Tuesday, 7 August 2012

Release It!: Design and Deploy Production-Ready Software


"A wise man learns by the mistakes of others, a fool by his own." - Latin Proverb

This book teaches you that “Feature complete” is not the same as “production ready”.

The summary at the end of the book sums up exactly what I feel about software development

Change is the defining characteristic of software. That change – that adaptation – begins with release. Release is the beginning of the software's true life; everything before the release is gestation.

This book shows you how to really think about the design decisions that you make in any project.

Release 1.0 is the beginning of your software's life. Your quality of life after 1.0 depends on choices you make long before that vital milestone.

The reality of most software is that we mean well when we build it, however we often get this wrong.

New software emerges like a new university student, full of optimistic vigour, suddenly facing the harsh realities of the world outside the development environment. Things happen in the real world that just don't happen during development, usually bad things.

The book is broken down into four sections:
  1. Stability
  2. Capacity
  3. General Design Issues
  4. Operations

Stability

The book defines stability as follows:

A stable system is one that keeps processing transactions, even when there are transient impulses, persistent stresses, or component failures disrupting normal processing.

An impulse is a rapid shock to the system and stress is a force applied to the system over an extended period.

Sudden impulses and excessive strain can trigger catastrophic failure. These failures can expose cracks in the system. These cracks are called failure modes. When a catastrophic failure occurs there is always chain of failure that caused it. One has to realise that the events are not independent as there is always a layer of coupling.

Some interesting Stability Anti-patterns:
  1. Blocked threads – Don't hold onto resources.
  2. Attacks of Self-Denial – kicking yourself while you are down.
  3. Unbalanced capacities – Make sure that all systems can take each others load.
  4. Slow Responses – These usually result from excessive demand.

To combat these here are some interesting Stability patterns:
  1. Use Time-outs – Now and forever networks will always be unreliable, well-placed time-outs provide fault isolation.
  2. Circuit Breaker – Protect your system from all manner of integration points problems. If the integration point is down stop calling it!
  3. Fail Fast – If your system can't meet it's SLA inform callers quickly. Check resource availability at the start of the transaction.
  4. Test Harness – Make sure that you simulate real-world failure modes. A great system for this is the recent is Chaos Monkey

By understanding the stability anti-patterns and the stability patterns described in the book one can prevent these cracks propagating through our layers in the system.

Capacity

The book defines capacity as follows:

Capacity is the maximum throughput a system can sustain, for a given workload, while maintaining an acceptable response time for each individual transaction.

Throughput describes the number of transactions the system can process in a given time span.

The hardest thing about dealing with capacity is working with non linear effects. In every system, exactly one constraint determines the system's capacity. It is important to understand these constraints.

Along with capacity comes some myths. I really never thought about these:
  1. CPU is cheap – In reality 250 milliseconds per transaction adds up to 69.4 hours of CPU time every day.
  2. Storage is cheap – Storage is a service not a device.
  3. Bandwidth is cheap – Dynamically generated pages tend to have a lot of junk in it. 1K of junk per page equates to 1GB of junk with 1 million page views a day.

Some interesting Capacity Anti-patterns:
  1. AJAX Overkill – Don't return small HTML and then send 400 request back to your server to get the reset. Best to return the JSON to the browser on the first request.
  2. The Reload Button – Fast sites don't provoke the user into hitting the Reload button.
  3. Cookie Monsters – Don't store your database in a cookie.

To combat these here are some interesting Capacity patterns:
  1. Use Caching Carefully – Limit your cache size and cache expensive objects.
  2. Pre-compute Content – If generating the content is expensive, process it offline.

I recently tried to apply the wasted space remover pattern in one of our projects. I was able to remove just under 10k worth of white-space (though I did manage to introduce bugs which frustrated the team). However after discussing with the team compression seems to take care of most of it. I still think it is important for clients that don't support compression (I know there are less and less every-time). This article seems to have some great statistics around why you shouldn't bother.

By understanding the capacity anti-patterns and the capacity patterns described in the book one can understand how to fine tune the system. This is achieved by an ongoing process of monitoring.

Capacity is fundamentally a measure of how much revenue the system can generate during a given period of time.

General Design Issues

There are many great topics in this section, however the one that I found really interesting is availability.

Availability of a system is typically measured as a factor of its reliability - as reliability increases, so does availability. However, no system can guarantee 100.000% reliability; and as such, no system can assure 100.000% availability – Wikipedia

An interesting take on availability is discussed in one of stability anti-patterns called SLA inversion.

SLA inversion states that unless every one of your dependant systems is engineered for the same SLA you must provide, then the best you can possibly do is the SLA of the worst dependant system.

It gets even worse than that statement. If built naively the probability of a system failing is the joint probability of a failure in any component or service. This means that if your system has five external services that each have 99.9% availability then the best your system can do is 99.5% (a little unclear on the maths would be great if someone pointed me in the right direction)

Operations

This chapter begins with a great story around when it rains it pours and how they dealt with it. Really interesting. The topic that really meant something to me in this section was Transparency.

Experienced engineers on ships can tell you when something is about to go wrong by the sound of the giant diesel engines. Transparency refers to the qualities that allow operators, developers and business sponsors to gain understanding of the systems historical trends, present conditions, instantaneous state and future projections.

Designing for transparency is really important as adding transparency late in the development is about as effective as adding quality.

Some great ideas around transparency are as follows:
  1. Monitoring and reporting systems should be built around your system, not in it. Better to expose than to couple to a service.
  2. Make sure you discuss what triggers alerts.
  3. Logging is still very important to this day and what you log is more important. A pet hate of mine is a system that tells you everything is OK in log files. Log file should only be used as a way to see what is going wrong with the system (what are your thoughts around this?).
  4. It is important to also get the logging levels right. I personally think that in production nothing over WARNING should be allowed.
  5. Understanding all the messages your system will produce is important. This is easier if you built the whole application. Message codes simplifies the communication between development and operations.
  6. Remember that in the end all of your decisions need to be understood by humans. When stressful situations occur the last thing you want is to try to decipher what the system is trying to tell you.

Conclusion

This has been a fantastic read and I really recommend it to anyone that wants to really think about what happens to your system once it goes in the wild. A lot of the issues these days are being addressed by cloud providers. This books really shows some of the early work that the DevOps movement is trying to solve so I applaud it. If you want more information check out this blog.

Tuesday, 24 July 2012

Introduction

“I’ve failed over and over and over again in my life and that is why I succeed.” - Michael Jordan

I have always wanted to start writing a blog about technical information that I find interesting and have been curious in writing having been inspired by many people. Hopefully these topics are of interest to you. 

So a little about me. I have been in the IT industry for the last 12 years and I can say that I am obsessed with my line of work, for a more detailed look check out LinkedIn. Some topics that interest me are:

  1. Agile software development
  2. Lean software development
  3. DevOps
  4. Continuous delivery
  5. Behavior-driven development
  6. Agile Architecture
  7. Lean Architecture
I am a fanatic at reading books. I love learning from people that are smarter than me. I thought I would take this forum to summarise what I have learnt and at the same time improve on my writing. I am very excited on the journey.